
Securing the AI software supply chain: from asset inventories to agent permissions
To govern AI software supply chains, the first step is to place code dependencies, models, data, frameworks, tools, and agent interfaces into a single asset view; then connect these assets to access control, permissions, testing, change management, and incident response processes. Without controls in operation, it remains impossible to answer what agents can do, where data will go after changes, or whether revalidation is needed post-change.
AI governance must reach engineering objects
The 2026 World Artificial Intelligence Conference & High-Level Meeting on Global Governance of Artificial Intelligence has made security, reliability, and controllability key topics in AI governance. For R&D teams, these goals need to be converted into engineering problems that can be recorded and verified: where models come from, how training or fine-tuning data is managed, which frameworks and external services are used, what permissions agents have, and whether anomalies can be traced back to specific versions.
The supply chain now extends beyond code and components
Traditional SBOMs primarily document software packages, versions, dependencies, and licenses. AI systems continue to leverage these software assets but also incorporate model weights, datasets, training and inference frameworks, prompt templates, vector libraries, plugins, Skills, MCP services, external APIs, and agent tools. Any object substitution can alter the system's security perimeter.
For example, a business AI agent might follow instructions differently even if application code remains unchanged when its model version is updated; adding a data source could introduce new sensitive information; and integrating an MCP service may expand the range of executable actions. Traditional dependency lists do not capture these changes' interconnections, so organizations need to extend their software supply chain records into asset relationships with AI systems.
- Code and open-source dependencies: component name, version, source, license, and known vulnerabilities
- Models and weights: provider, version, acquisition location, validation information, and permitted uses
- Data assets: source, processing method, scope of use, and sensitivity labels
- Frameworks and runtime environments: software stacks used for training, inference, orchestration, and deployment
- Tools and interfaces: plugins, Skills, MCP services, external APIs, and their invocation permissions
- Change records: who replaced which object at what time, with what validations and tests conducted
Three emerging risks to watch
Model poisoning
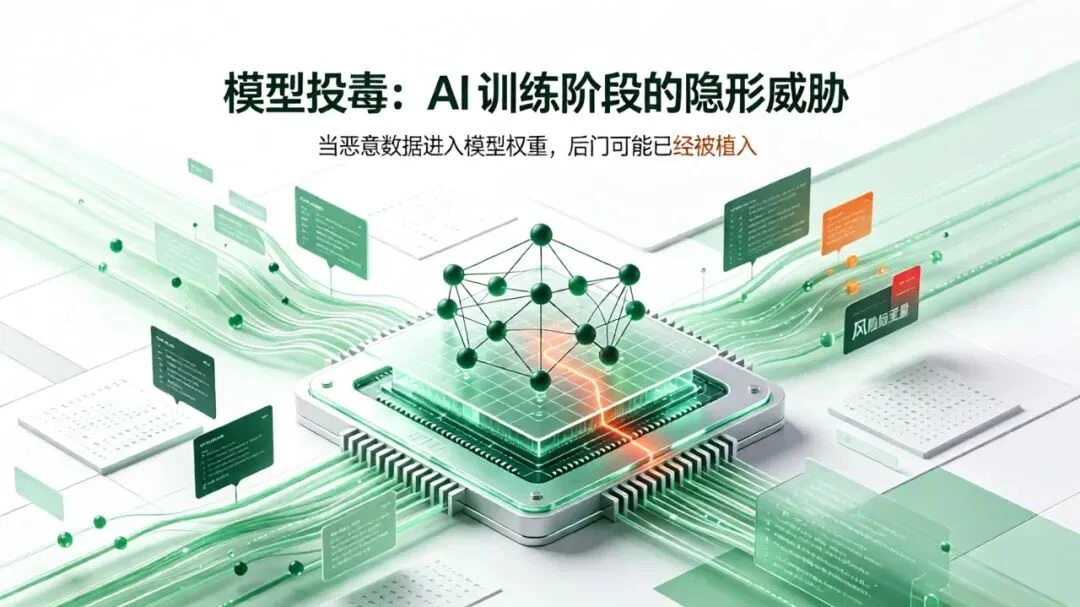
Risk may be introduced into the training data, fine-tuning process, or model weights and manifest as anomalous outputs under specific input conditions. When checking, records should not only include the model name but also retain version information, sources, integrity checks, details of training or fine-tuning, and validation results.
Verifying model risks: first confirm that the model files match the records of the publishing entity, then check if the organization has undergone secondary training or quantization. Use a test set covering normal tasks, boundary inputs, and adversarial inputs to record behavior differences. If the model is provided by an external API, also document service versions, regions, data retention policies, and notification mechanisms for supplier changes.
Tool poisoning and dependency contamination
Training frameworks, data processing tools, inference engines, plugins, and third-party packages can all serve as propagation pathways. Organizations need to confirm the download sources, lock versions, verify integrity, and document the relationships between images, build environments, and deployed products. Scanning only business code cannot cover these upstream objects.
This inspection includes both conventional component vulnerabilities and license checks, as well as scenarios involving the execution of remote code during model loading, automatic installation of plugins with unknown dependencies, and inclusion of unannounced tools within container images. The team should retain locked files, artifact summaries, build logs, and deployment lists to enable issues to be pinpointed to specific environments.
Agent goal hijacking and excessive permissions
The AI system receives natural language content and invokes external tools. Malicious or unverified context can alter its behavior if agency permissions are too broad, leading to further data read/write operations or external actions. OWASP has identified Excessive Agency as one of the risks for generative AI applications, focusing on whether functionality, permissions, and autonomy exceed what is needed for a task. OWASP Excessive Agency
Therefore, agent evaluations cannot be limited to whether the content is correct. They should also follow the 'input content → model judgment → tool selection → parameter generation → actual execution → result feedback' chain to confirm that untrustworthy content cannot bypass authorization rules and verify if the system safely stops when an execution fails or returns an abnormal result.
Start with an updatable AI asset inventory
An AI-BOM can consolidate models, datasets, software packages, and tools into a unified record, describing the relationships between them. The SPDX 3 model provides a framework for AI objects, serving as a reference for exchanging and organizing information.
- Establish stable identifiers for each asset type, recording names, versions, sources, and responsible parties.
- Connect models to the relationships between datasets, frameworks, plugins, and runtime environments.
- Preserve license information, usage restrictions, integrity checks, and risk assessments.
- Ensure asset records can correspond to specific product versions, deployment environments, and release dates.
- Trigger re-evaluation after changes in dependencies, models, or permissions, rather than conducting a one-time inventory.
Connect the inventory to approval and change workflows
Governance value only emerges when the AI-BOM is integrated into actual processes. When new models, datasets, or tools are introduced to a project, they should be vetted for source, licenses, completeness, and intended use before being granted access; permissions and testing scopes can then be configured. Asset replacements, upgrades, or retraining require identifying differences and determining which security conclusions need to be re-verified.
Each judgment should be able to answer four questions: Which version is being checked? What rules or test sets are used? Who made the decision? And what release version does the result correspond to? This ensures that the AI-BOM can evolve from static lists into an index of evidence connecting research, testing, deployment, and auditing.
Control agent tools and permissions
In addition to making assets visible, it is also important to limit the actions that AI agents can perform. This includes tool registration, identity verification, access scope, parameter validation, manual confirmation, and logging of execution logs. Continuous control should be established for these features. High-risk operations should use the least amount of permissions, and appropriate levels of manual review should be set based on data sensitivity and business consequences.
- Function boundary: give AI agents access only to the tools required for the task
- Data boundary: limit the data that can be read, written or transmitted
- Execution boundary: require confirmation for deletion, publication, payment and permission changes
- Network boundary: restrict external services, domains and API calls
- Audit boundary: record inputs, model versions, tool calls, returned results and final actions
Build validation into the change workflow
AI systems' risk conclusions can change with the model, prompt, data, tools, and permissions. Effective practices involve integrating security validation into development and release processes, rechecking asset differences, permission impacts, and key task performance after each significant change. Retain reproducible test inputs and results.
- Compare model versions, dependencies, data lists, and tool sets between new and old versions.
- Identify newly added permissions, external connections, and high-impact operations.
- Perform security tests such as prompt injection, anomalous contexts, and tool misuse.
- Review if failure paths could lead to unauthorized access, sensitive data leakage, or irreversible actions.
- Associate findings, resolutions, exceptions, and retests with the release version.
Post-launch monitoring also requires referencing these asset relationships. In case of anomalous tool calls, unauthorized attempts, or model behavior drifts, teams should be able to quickly identify affected models, agents, deployment environments, and user scopes, tracing back recent dependencies, prompts, and permission changes. Without versioned asset records, incident response relies solely on manual checks.
The role of AgentST in governance workflows
Within this governance framework, AgentST identifies and establishes relationships for models, datasets, frameworks, agent skills, tools, and MCP interfaces. It assists teams in checking security issues in dependency and call chains. Tool outputs need to be combined with the organization's access rules, permission management, test records, and manual judgments to form evidence usable for release and audit.
AI software supply chain security is not about adding a model list outside traditional component scanning. It requires organizations to manage asset sources, operational permissions, and continuous validation: knowing what the system consists of, understanding how each object affects it, and re-proving that critical boundaries remain effective after any change.